Beyond the Rulebook
Agent-based models turn explicit rules into complex collective behavior. Interpreting incomplete information or an ambiguous request can require additional rules and special cases. This project explores how decision models can interpret those situations and return structured actions within a spatial simulation.
The work developed through two studies: a comparison of model responses at a subway information desk, followed by a campus experiment that places shared reasoning at decision nodes throughout a network.
01 · Train station: comparing decision models
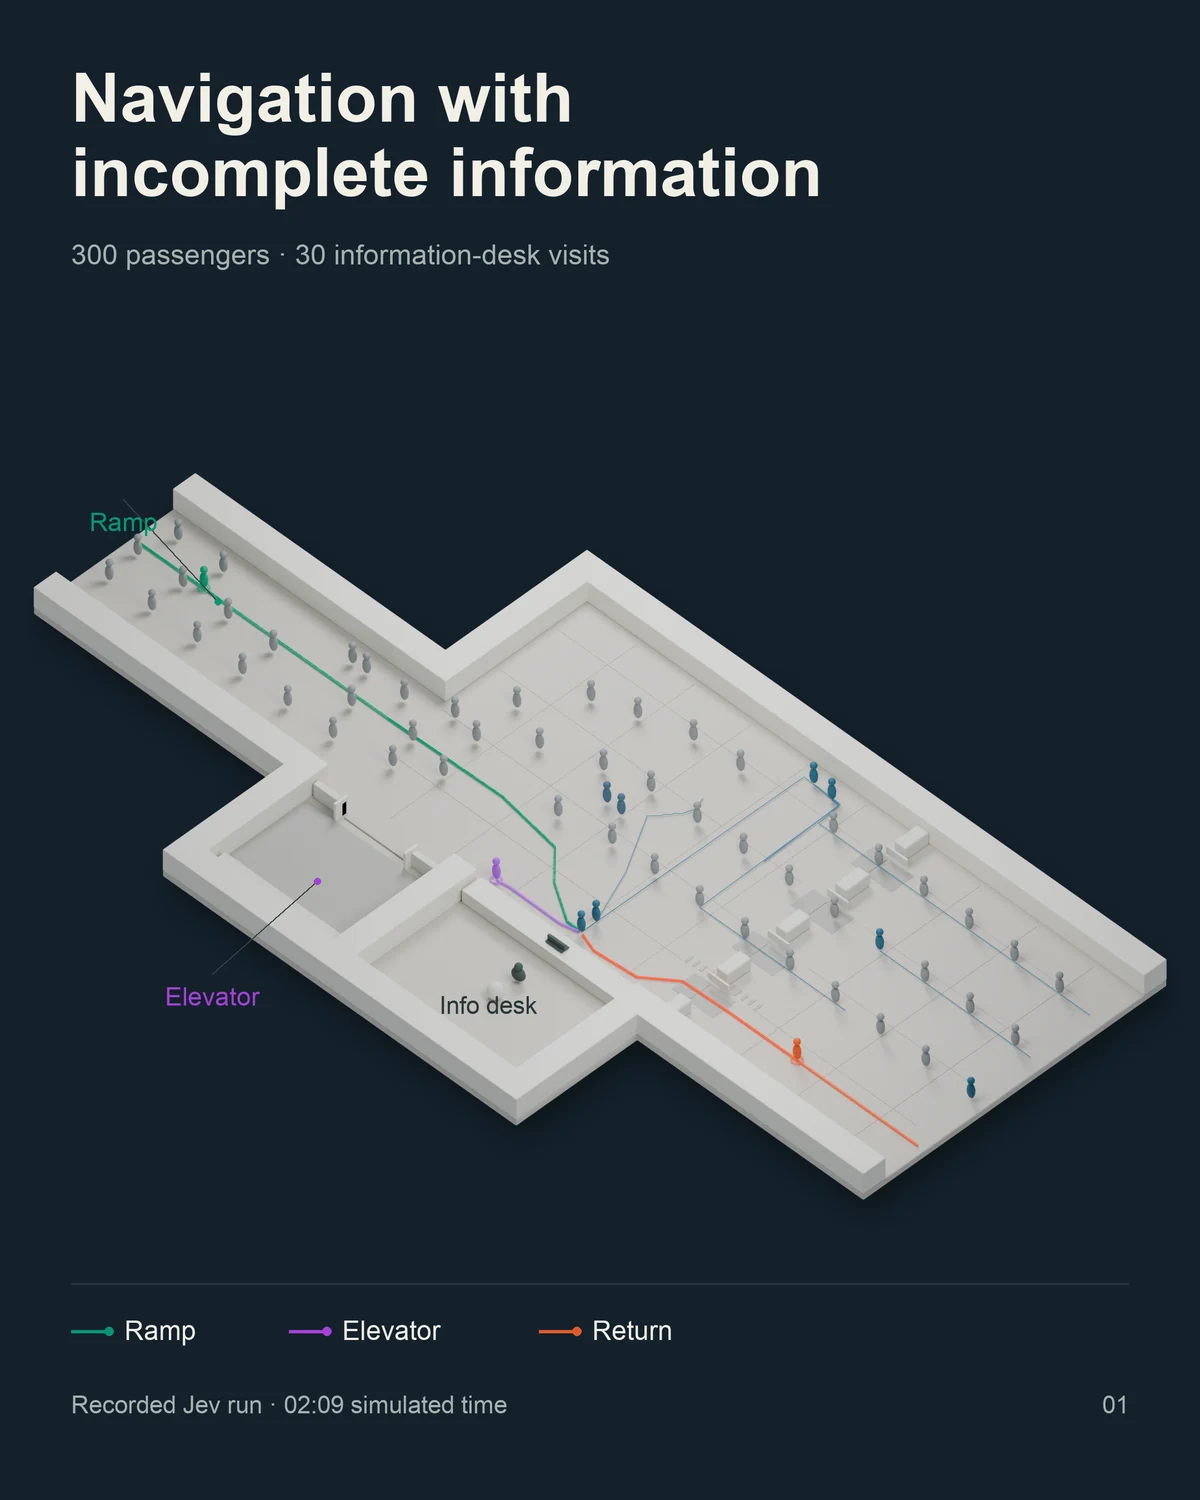
The first study modeled a simplified New York City subway station in GAMA. 300 passengers arrived over three minutes; 30 visited an information desk. Requests included finding the airport train, reaching a platform without stairs, and discovering that the intended service departed from another station.
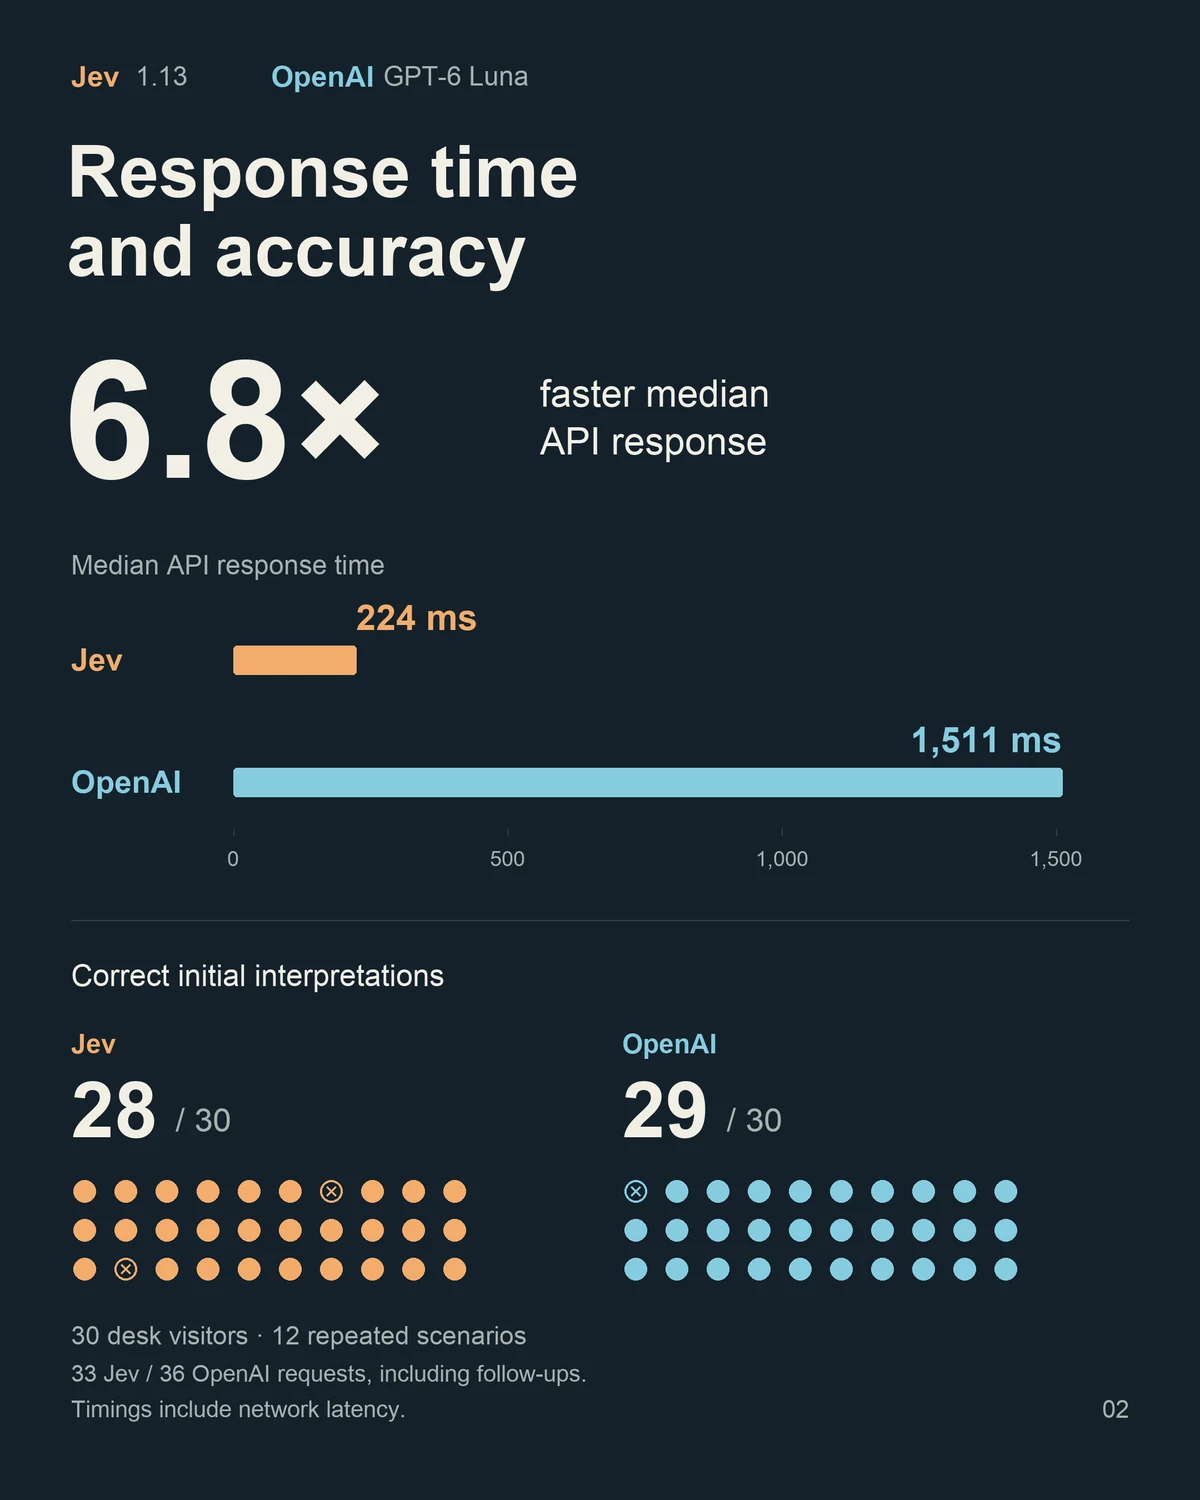
Jev 1.13 and OpenAI GPT-6 Luna received identical initial requests and equivalent structured answer choices. Shared routing rules translated the responses into movement, with follow-up questions when information was unclear.
Jev's median API response was 224 ms, compared with 1,511 ms for GPT-6 Luna: approximately 6.8 times faster in this test. Initial interpretation accuracy was 28/30 and 29/30, respectively. Final route assignments agreed after clarification. The Jev scenario ended about 20% earlier in simulated time, with identical assumed human exchange times added to the recorded API delays.
02 · Campus accessibility: cognitive networks
The second study asks: can the network itself become a decision arbitrator? Agents retain a destination, an accessibility profile, and simple movement rules. Interpretation happens at designated network nodes, where each pedestrian's needs meet the information available at that location.
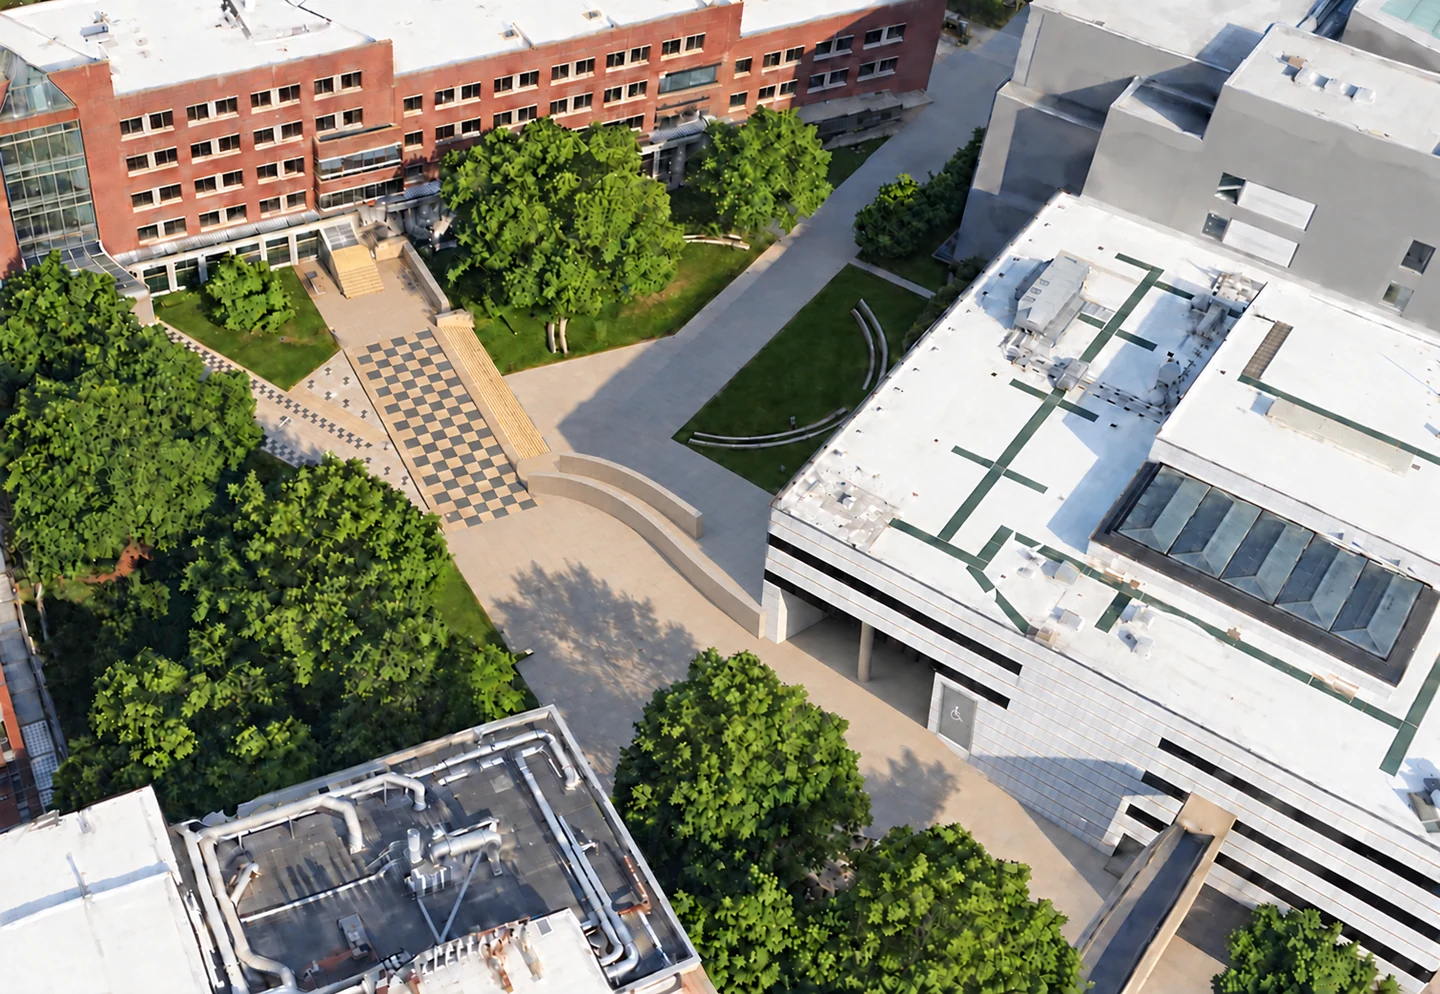
The public space between the MIT Media Lab and MIT's eastern campus was modeled with a proposed ramp and an assumed internal lift connection alongside the existing stairs. These are modifications to the simulated environment, allowing alternative access arrangements to be explored.
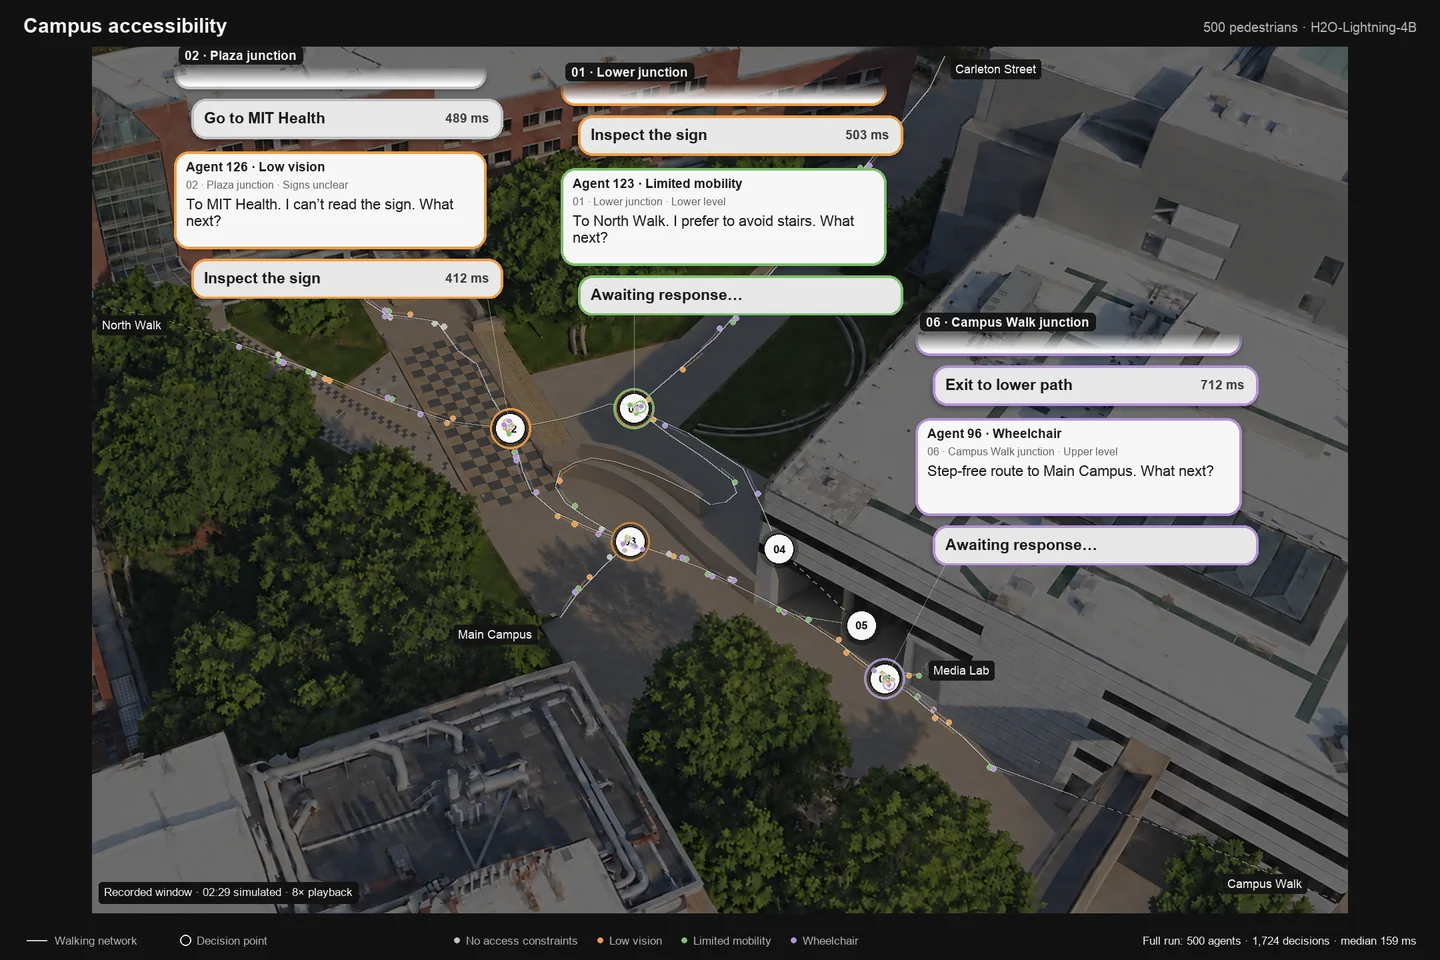
500 pedestrians approached from six origins with four profiles: no access constraints, low vision, limited mobility, and wheelchair users. At six decision nodes, a shared H2O-Lightning-4B model running locally on TARS interpreted the pedestrian's destination, preferences, current level, visible connections, readable signs, and recent actions.
A request such as “How do I reach MIT Health without stairs?” is resolved by selecting a supplied local action: inspect a sign, take the ramp, enter the lift lobby, or continue along a path. Available choices and observations change at each node. GAMA handles movement between decisions; the model receives local symbolic information rather than the aerial photograph or a precomputed trip route.
The run recorded 1,724 native decisions, with a median API response of 159 ms and a 95th percentile of 685 ms. All 500 pedestrians reached their destinations. Completion did not mean perfect behavior: eight limited-mobility agents chose stairs despite their stated preference. Wheelchair agents never chose stairs and used the lift for all 41 changes of level.
The video above shows a continuous 160-second recorded window at 8× playback. Three message streams display 24 selected exchanges across all six decision nodes. Colored outlines identify accessibility profiles; the displayed questions summarize recorded inputs, while replies represent actual structured choices. Message visibility is held for reading independently of the measured API duration.
Why make the network cognitive?
Knowledge is attached to the place where it matters. A closed lift, a new ramp, or an unclear sign could be described once at a node, then interpreted differently for each arriving pedestrian's needs and destination. This reduces the need to prescribe a separate response for every combination of person, destination, and local condition.
The network becomes a shared layer for interpreting uncertainty, while individual agents remain simple. It also makes decisions observable at specific places, helping identify where guidance succeeds, where preferences are missed, and how changes to access or information might affect many individual journeys.
Scope of the experiments
These are functional demonstrations, not calibrated crowd or accessibility assessments. Geometry, movement speeds, and internal lift transfers are schematic. API timings include serving and request overhead; simulated time is a separate measure. The station comparison and campus run use different scenarios and models, so their timings are not a controlled comparison. No independent accuracy benchmark or comparison engine was run for the campus study.